Automating Bare-Metal GPU Server Setup: Ansible Playbook for Drivers, Docker, and CUDA 12
Complete Ansible playbook for automated provisioning of bare-metal GPU servers with NVIDIA drivers, Docker Engine, and Container Toolkit.
Read Architecture →Deep technical guides on deploying private LLMs, securing AI workloads, and automating cloud and on-prem infrastructure with Docker, Kubernetes, OPNsense, and Terraform.
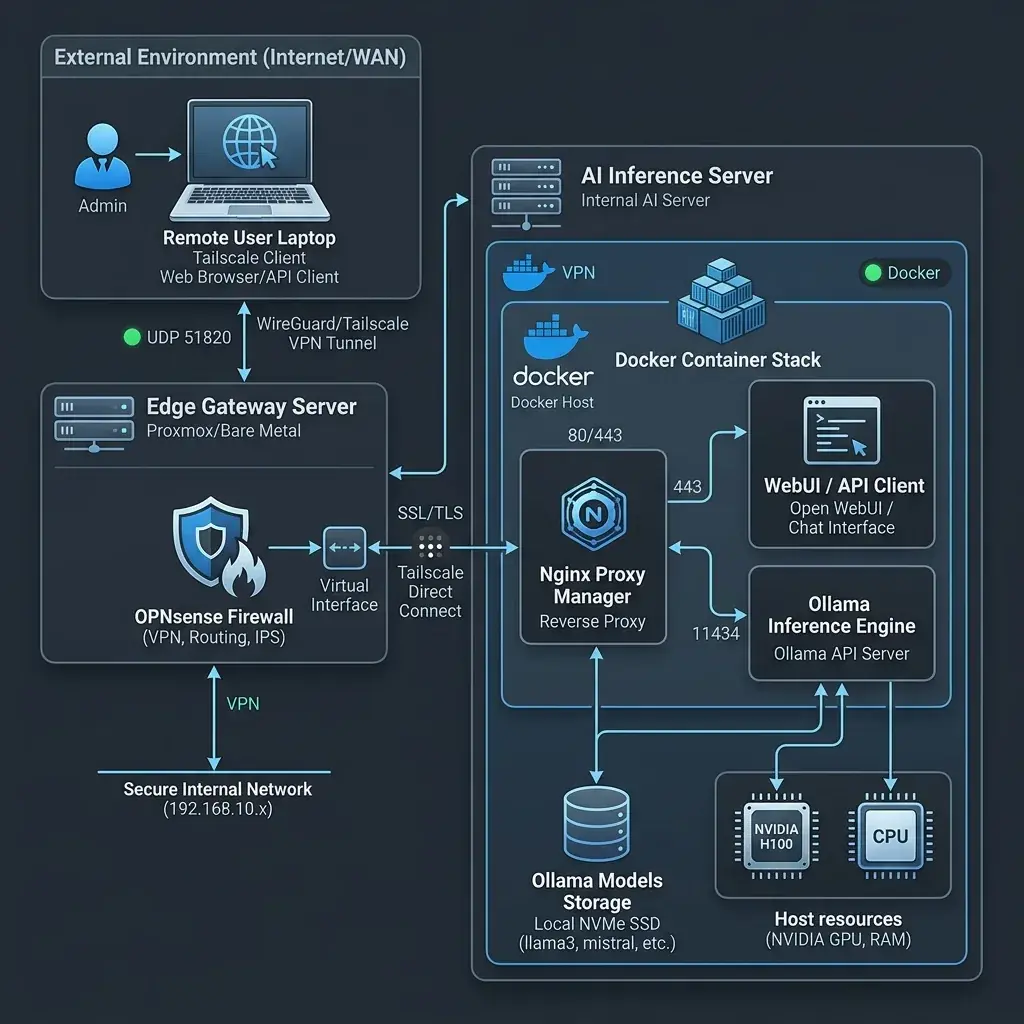
Complete Ansible playbook for automated provisioning of bare-metal GPU servers with NVIDIA drivers, Docker Engine, and Container Toolkit.
Read Architecture →Deploy models on consumer GPUs or enterprise clusters without vendor lock-in. Full VRAM utilization guides.
Isolate inference nodes via strict VLANs and deep packet inspection using OPNsense and Tailscale.
Keep proprietary code and corporate documents off public APIs. Full control over the RAG pipeline.
Complete Ansible playbook for automated provisioning of bare-metal GPU servers with NVIDIA drivers, Docker Engine, and Container Toolkit.
Production architectural blueprint for deploying NVIDIA GPU Operator on K3s Kubernetes clusters to orchestrate GPU-accelerated container pods.
Reference architecture for private LLM workloads. Includes Docker Compose, OPNsense VLAN isolation, and Terraform provisioning.
Complete production-ready architecture blueprint for building an isolated, zero-trust home lab or edge server for private LLMs.
Architecture guide for configuring an all-in-one sovereign AI server running virtualized OPNsense, Docker containers, databases, and GPU passthrough.
Step-by-step technical guide to exposing AMD Radeon & Instinct GPUs (/dev/kfd and /dev/dri) to Docker containers using ROCm.
Technical comparison of VPS and GPU cloud providers for self-hosted AI agents, LLM inference, and Ollama. Compare CPU vs GPU nodes, VRAM, RAM, and costs.
Join 5,000+ engineers receiving our weekly deep dives on securing, scaling, and automating private AI workloads.